Measures of Spread (Continued) and Measures of Position
Sections 3.2 & 3.3Last time ended on the variance, measured in squared units. We start by taking its square root.
Compute the standard deviation of a population and a sample
 Definition
Standard Deviation
Since variance is calculated using squared deviations, its units are the squared units of the data. However, it’s often more practical to use a measure of spread with the same units as the data. This is achieved by taking the square root of the variance, resulting in the standard deviation.
 Example
: San Francisco Temperatures
Recall: the population variance of these temperatures is degrees squared.
What is the standard deviation, in degrees?
| Jan | Feb | Mar | Apr | May | Jun | Jul | Aug | Sep | Oct | Nov | Dec | |
| San Francisco | 51 | 54 | 55 | 56 | 58 | 60 | 60 | 61 | 63 | 62 | 58 | 52 |
= 3.753 degrees: back in the units of the data.
 Calculator
The 1-Var Stats output, in the Statistics Calculator and on the TI-84 Plus, gives both the sample standard deviation and the population standard deviation.
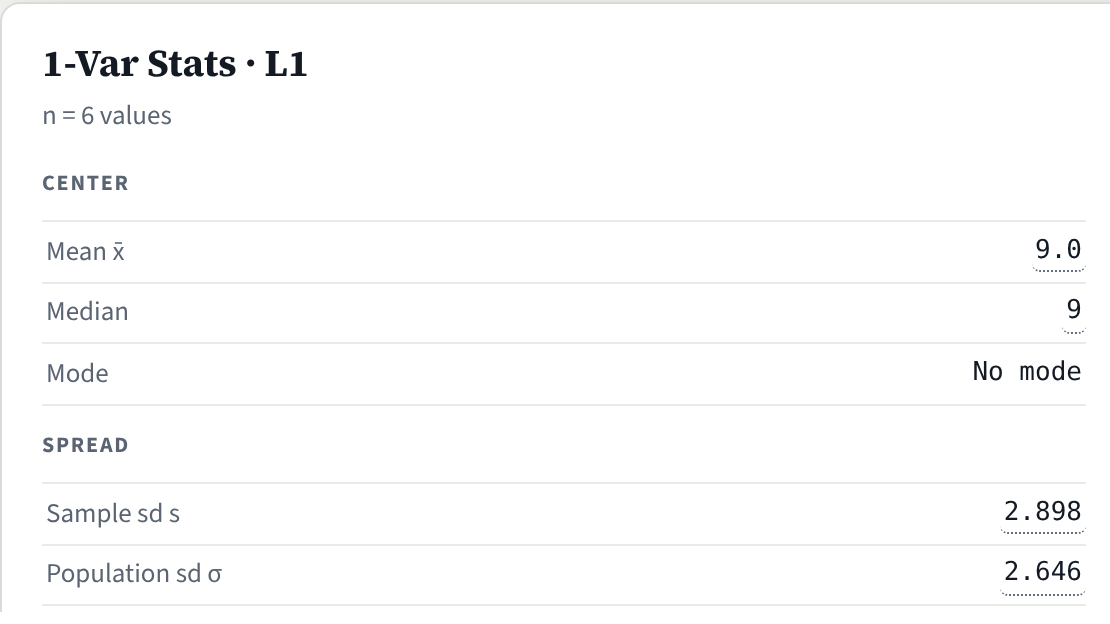
The Standard Deviation is Not Resistant
Like the mean, it is significantly affected by extreme values.
Use The Empirical Rule to summarize data that are unimodal and approximately symmetric
The Empirical Rule
When a data set has a bell-shaped histogram, it is often possible to use the standard deviation to provide an approximate description of the data using a rule known as The Empirical Rule.
Approximately 68% of the data will be within one standard deviation of the mean.
to 40 to 60Approximately 95% of the data will be within two standard deviations of the mean.
to 30 to 70All, or almost all, of the data will be within three standard deviations of the mean.
to 20 to 80ExampleExample: The Empirical Rule
Projections of the percentage of the population aged 65 and over are given for each state and the District of Columbia. Describe the population using the Empirical Rule.
| 14.1 | 14.3 | 14.4 | 17.8 | 12.0 | 14.9 | 12.6 | 13.7 | 12.8 | 13.8 | 13.7 | 12.4 | 13.8 |
| 14.1 | 13.3 | 14.3 | 16.0 | 8.1 | 11.5 | 14.1 | 10.2 | 12.4 | 13.4 | 15.6 | 12.8 | 13.9 |
| 12.3 | 14.1 | 15.3 | 13.0 | 13.6 | 10.5 | 12.4 | 13.5 | 13.9 | 10.7 | 11.5 | 14.3 | 12.7 |
| 13.1 | 12.2 | 12.4 | 15.0 | 12.6 | 13.6 | 13.7 | 15.5 | 14.6 | 9.0 | 12.2 | 14.0 |
Check the condition first: is the histogram bell-shaped?
The histogram is bell-shaped, so the Empirical Rule applies.
CalculatorExample: The Empirical Rule
Enter the 51 values in the Statistics Calculator and choose Summarize.
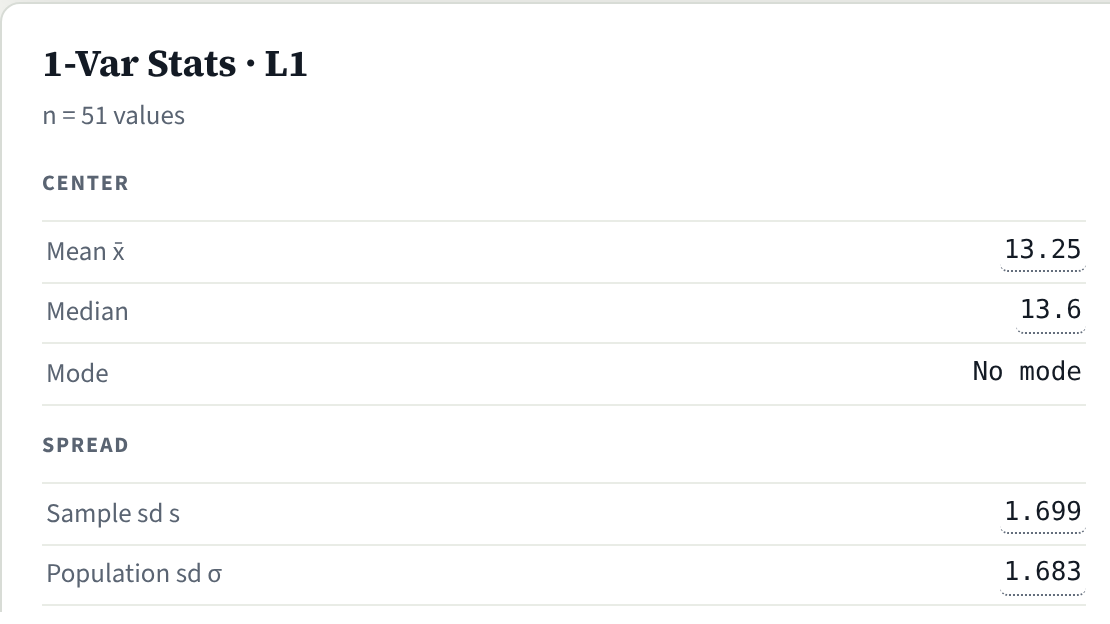
These 51 values are the whole population, so and .
The calculator labels the mean and also prints ; for a population, we use and .
ExampleExample: The Empirical Rule
We compute six quantities:
Recall: ,
Approximately 68% of the data values are between 11.57 and 14.93.
Approximately 95% of the data values are between 9.88 and 16.62.
Almost all of the data values are between 8.20 and 18.30.
 Check Your Understanding
Commute Times
Commute times in a city have a bell-shaped histogram, with mean minutes and standard deviation minutes.
About what percent of commute times are between 24 and 36 minutes?
About 68%. 24 and 36 are one standard deviation from the mean: and . 2About 95% of commute times are between what two values?
18 and 42 minutes. · 3All, or almost all, commute times are between what two values?
12 and 48 minutes. ·Section 3.2: Measures of Spread
The square root of the variance, so it carries the same units as the data.
For a bell-shaped data set, approximately 68% of the data lies within one standard deviation of the mean, approximately 95% within two, and all, or almost all, within three.
Measures of Position
Section 3.3Compute and interpret -scores
Definition-Score
Let be a value from a population with mean and standard deviation . The -score of is:
The -score of an individual data value tells how many standard deviations that value is from its population mean.
For example, a value one standard deviation above the mean has a -score of and a value two standard deviations below the mean has a -score of .
 Example
: Comparing Heights
A study shows the average height for U.S. men is 69.4 inches () and for women is 63.8 inches ().
Who is taller relative to their gender: a 73-inch man or a 68-inch woman?
The woman is taller, relative to the population of women’s heights.
The Two Heights on One Scale
Finding a Value with a Given -Score
To find a value from a given -score, multiply the -score by the standard deviation, then add the result to the mean.
Data from the National Health and Nutrition Examination Survey show that for U.S. adults, the mean cholesterol level is mg/dL (). What is the cholesterol level for someone with a -score of 1.5?
The cholesterol level is 266 mg/dL.
The Empirical Rule & -Scores
The Empirical Rule, in -scores
About 68% of the data have -scores between −1 and 1.
About 95% have -scores between −2 and 2.
All, or almost all, have -scores between −3 and 3.
 Check Your Understanding
-Scores at the Airport
The Wall Street Journal reports that the average maximum distance from check-in to the gate at top U.S. airports is miles ( miles).
The maximum distance at the Seattle-Tacoma International Airport is 0.57 miles. What is the -score for this distance?
2What distance would have a -score of 1?
milesCompute the quartiles of a data set
Quartiles
We’ve learned how to compute the mean and median of a data set as measures of the center. Sometimes, it is useful to compute measures of position other than the center.
Quartiles divide a data set into four approximately equal pieces.
The first quartile, , separates the lowest 25% of the data from the highest 75%.
The second quartile, , divides the data so that 50% is below and 50% is above, essentially representing the median.
The third quartile, , separates the lowest 75% of the data from the highest 25%.

Suppose…
The third quartile of the lifespan of a certain type of Goldfinch is approximately 72 months.
This means…That 75% of this type of Goldfinch do not live for more than 72 months.
Or 25% of them live for more than 72 months.
ExampleExample: Computing Quartiles
The table below shows the February annual rainfall in Los Angeles over several years (in inches). Calculate the quartiles.
| 0.00 | 0.03 | 0.08 | 0.16 | 0.17 | 0.20 | 0.29 | 0.56 | 0.70 | 0.79 | 0.83 | 0.92 | 1.22 | 1.30 | 1.48 |
| 1.64 | 1.72 | 1.90 | 2.37 | 2.84 | 3.06 | 3.12 | 3.21 | 3.29 | 3.54 | 3.57 | 3.58 | 3.71 | 4.13 | 4.17 |
| 4.27 | 4.37 | 4.64 | 4.89 | 4.94 | 5.54 | 5.59 | 6.10 | 6.61 | 7.96 | 8.87 | 8.91 | 11.02 | 12.75 | 13.68 |
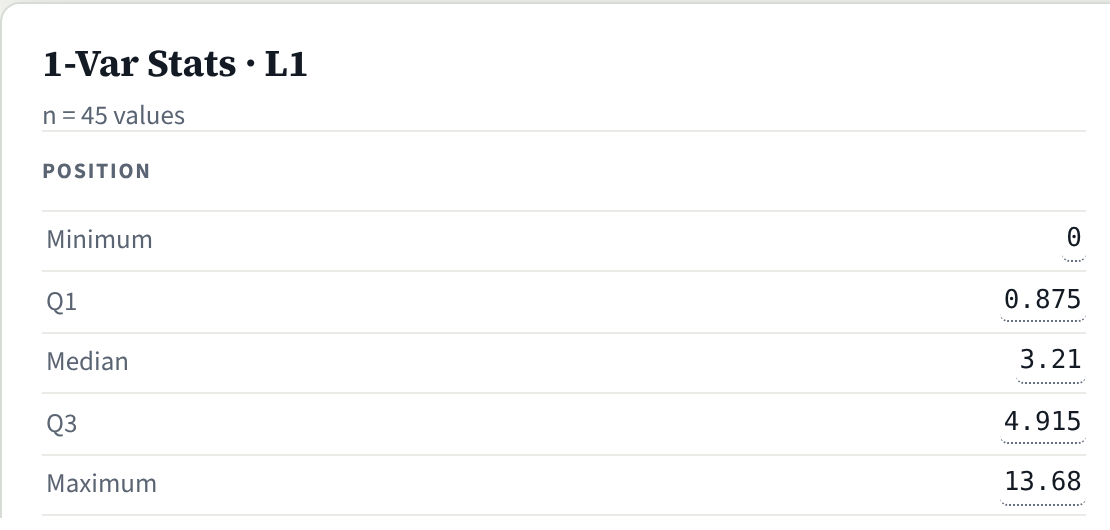
and .
Visualizing the Quartiles
Percentiles
Percentiles divide a data set into hundredths.
For any number between 1 and 99, the percentile separates the lowest 50% of the data from the highest 50%.
Visualizing Percentiles
 Check Your Understanding
The 10th Percentile
After getting her recent statistics exam score, Aminah boasted to her friends, “I scored in the 10th percentile of the class!”
Does Aminah have a reason to brag?
No. Scoring in the 10th percentile means 90% of the class scored above her.
Compute the five-number summary for a data set
DefinitionFive-Number Summary
The five-number summary of a data set consists of the median, the first quartile, the third quartile, the smallest value, and the largest value. These values are generally arranged in order.
CalculatorFive-Number Summary with Technology
The five-number summary is often part of the output when using technology.
Understand the effects of outliers
DefinitionOutliers
An outlier is a value significantly larger or smaller than most in a data set.
Some outliers arise from errors, like a misplaced decimal point, causing the value to stand out.
Other outliers are accurate and reflect the presence of extreme values in the population.
DefinitionInterquartile Range
One method for detecting outliers involves a measure called the Interquartile Range (IQR). The interquartile range is found by subtracting the first quartile from the third quartile: .
Any data value beyond the outlier boundaries may be an outlier.
ExampleExample: Outliers
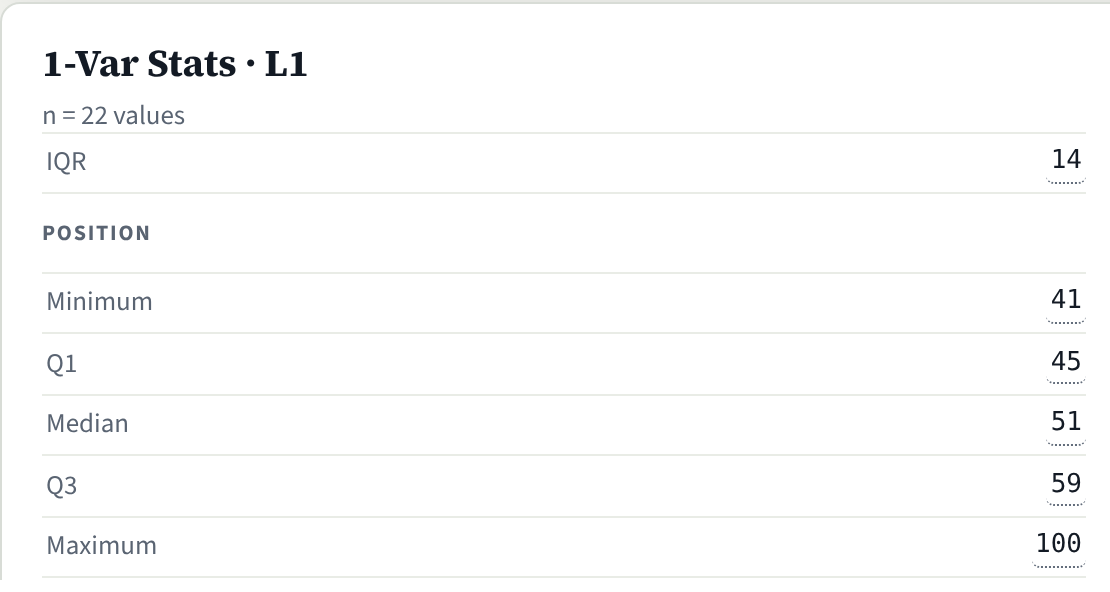
The table shows the number of students absent from school each day in January. Identify any outliers in the data.
| 65 | 67 | 71 | 57 | 51 | 49 | 44 | 41 | 59 | 49 | 42 |
| 56 | 45 | 77 | 44 | 42 | 45 | 46 | 100 | 59 | 53 | 51 |
From the Statistics Calculator: and .
The value 100 is an outlier because it is greater than 80.
Section 3.3: Measures of Position
The -score of an individual data value tells how many standard deviations that value is from its population mean.
Quartiles divide a data set into four approximately equal pieces; percentiles divide it into a hundred.
The five-number summary of a data set consists of the median, the first quartile, the third quartile, the smallest value, and the largest value.
One method for detecting outliers involves a measure called the Interquartile Range (IQR).
You Are Ready For:
3.2 HW: Measures of Spread
3.3 HW: Measures of Position